Solving Spark error: “Cannot broadcast the table that is larger than 8GB"

Error

Although I have already set crossJoin.enable to true and autoBroadcastJoinThreshold to -1, I still got an error.

spark = (
    SparkSession
    .builder.appName('my_spark')
    .config("spark.sql.crossJoin.enabled", "true")
    .config("spark.sql.autoBroadcastJoinThreshold", '-1')
    .getOrCreate()
)

java.util.concurrent.ExecutionException:
org.apache.spark.SparkException: Cannot broadcast the table that is larger than 8GB: 8 GB

This error is due to default PySpark broadcast size limit which is 8 GB.

Solution

There is no specific code or config we can set to solve this problem (at least I didn’t find one).

What we can do is to optimize our code.
Here are some of my ideas.

  • Use select(cols) or selectExpr(cols) to choose the columns we actually need before join to reduce the dataframe’s size.
  • Use filter(expr) to filter out what data we don’t need.
  • Use normal df1.join(df2) instead of using df1.join(broadcast(df2)).

I selected less columns of my dataframe (from 7 cols to 3 cols) to solve my problem.

Solving Spark error: “TaskMemoryManager: Failed to allocate a page"

Error

This error occurs endlessly during PySpark code running.

TaskMemoryManager: Failed to allocate a page.

Solution

I added one spark config in SparkSession that solved my problem.
Set autoBroadcastJoinThreshold to -1.

“spark.sql.autoBroadcastJoinThreshold": ‘-1’

Code example

spark = (
    SparkSession
    .builder.appName('my_spark')
    .config("spark.sql.autoBroadcastJoinThreshold", '-1')
    .getOrCreate()
)

Solving Spark error: “Decompression error: Version not supported" on GCP Dataproc

My gcloud command on terminal to create cluster

sudo gcloud dataproc clusters create my-project \
    --bucket my-bucket \
    --project my-gcp-project \
    --region asia-east1 \
    --zone asia-east1-b \
    --image-version=2.0-ubuntu18 \
    --master-machine-type n1-highmem-8 \
    --master-boot-disk-size 30 \
    --worker-machine-type n1-highmem-8 \
    --worker-boot-disk-size 100 \
    --num-workers 6 \
    --metadata='PIP_PACKAGES=xxhash' \
    --optional-components=JUPYTER \
    --initialization-actions gs://goog-dataproc-initialization-actions-asia-east1/python/pip-install.sh
    --subnet=default


Error

This error occurs during specific PySpark code running.

java.io.IOException: Decompression error: Version not supported

Solution

Change image-version from 2.0-ubuntu18 to 2.1-ubuntu20 can solve this version not supported error.

--image-version=2.1-ubuntu20 \

2023 年閱讀書單!9 本關於個人成長、思維突破、閱讀產出以及數據說服力的書

去年底看到不少人發表了一整年的讀書心得,有些書我覺得很不錯,順便也參考了博客來的 2022 年度暢銷榜和書評,收集整理出我自己在今年有興趣閱讀的書單,但不確定能看完幾本,希望是至少能有三到五本,有讀完的也會找時間寫一下讀書心得分享出來。


書單

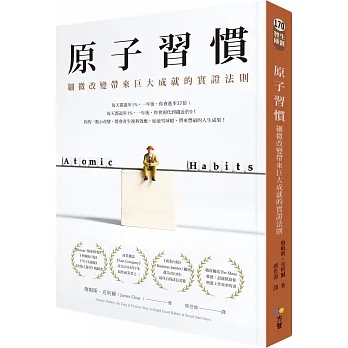
《原子習慣》

你的一點小改變、一個好習慣,將會產生複利效應

如滾雪球般,為你帶來豐碩的人生成果!

這本書已經買了一年,但還沒翻開,但因為實在是太多人都在推薦,同時又是博客來年度暢銷的 Top 1,決定今年還是把他列入目標之一,應該會優先讀它,希望自己能照裡面的方式,培養出讀書的習慣。


《逆思維》

想法轉個彎,人生路更寬!

翻轉危局的解答並不一定在前方,而在你的每一個「想不到」裡。

在博客來上有 55 個好評的熱門書籍,也是博客來年度暢銷的第 17 名,主要提倡「重新思考」這個概念,突破認知盲點。


《唐鳳的破框思考力》

天才唐鳳的思考軌跡,處處閃現破框的啟發與洞見的入口
開啟你思考的寬度,看世界的深度

這本書在去年九月底出版,馬上就看到各種推薦,目前在博客來已經有 24 個好評,主要也是強調突破框架、改變思考方式。

閱讀更多»

2022 年 Kaggle 資料科學 & 機器學習現況調查

每年底 Kaggle 都會在網站上做問卷調查,去年底的調查總共收集了 23,997 份來自 173 個不同國家的回覆,我這次用圖文整理翻譯了一些重點。

1. Kaggle 數據競賽平台現況

  • 資料科學家 > 1000 萬名
  • ML 競賽 300+ 場
  • 公開資料集數量 > 17 萬
  • 公開程式碼數量 > 75 萬

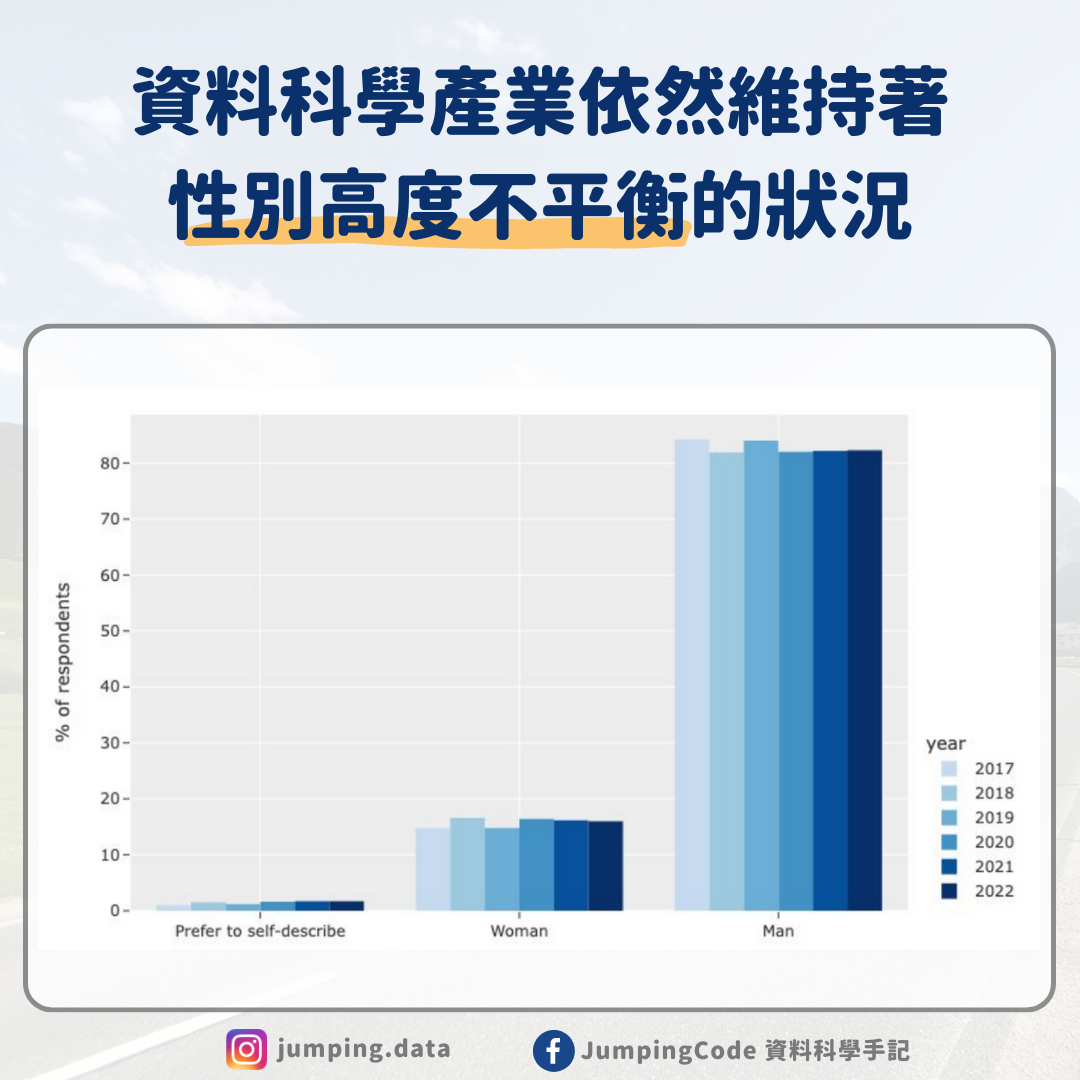
2. 性別趨勢

資料科學產業依然維持著性別高度不平衡的狀況

閱讀更多»